We keep certifying clinical AI on model accuracy scores, but the 2026 evidence shows the real safety problem lives in the clinician-plus-AI pair. Doctors follow confident AI advice even when it is wrong, and explanations do not protect them.
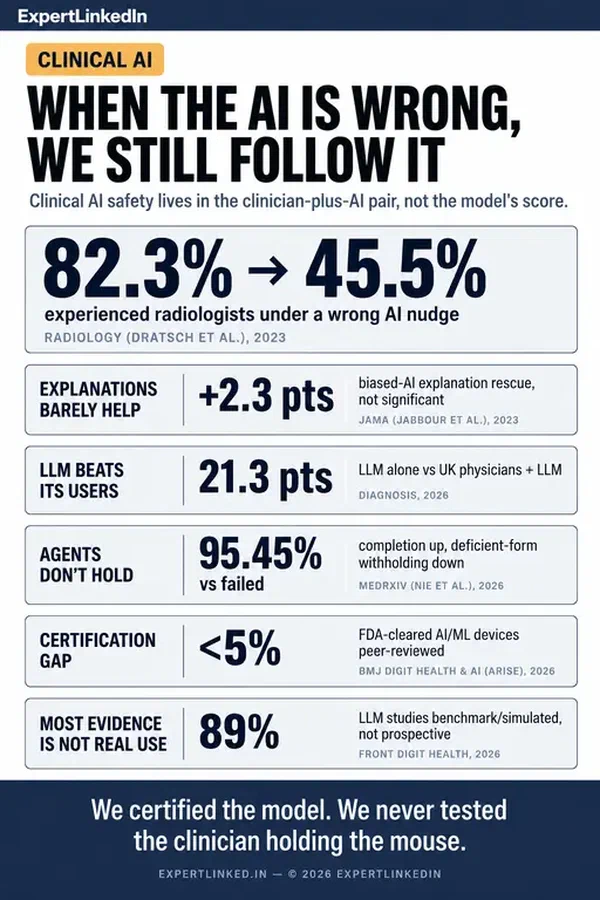
We keep certifying clinical AI on model accuracy scores, but the 2026 evidence shows the real safety problem lives in the clinician-plus-AI pair. Doctors follow confident AI advice even when it is wrong, and explanations do not protect them.
A strong average score can hide the patients and care settings where healthcare AI breaks. Skin-tone gaps, validation shortcuts, and weak postmarket monitoring make subgroup evidence more important than another headline AUROC.
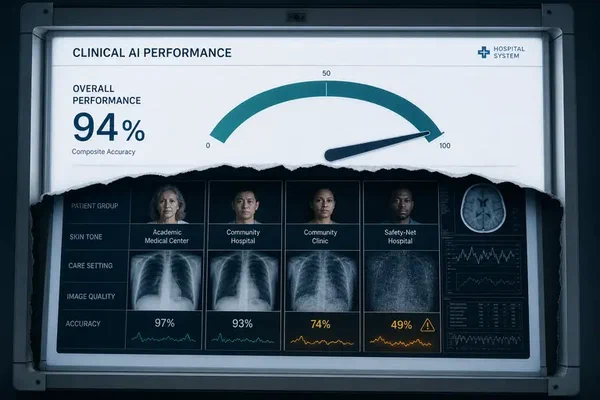
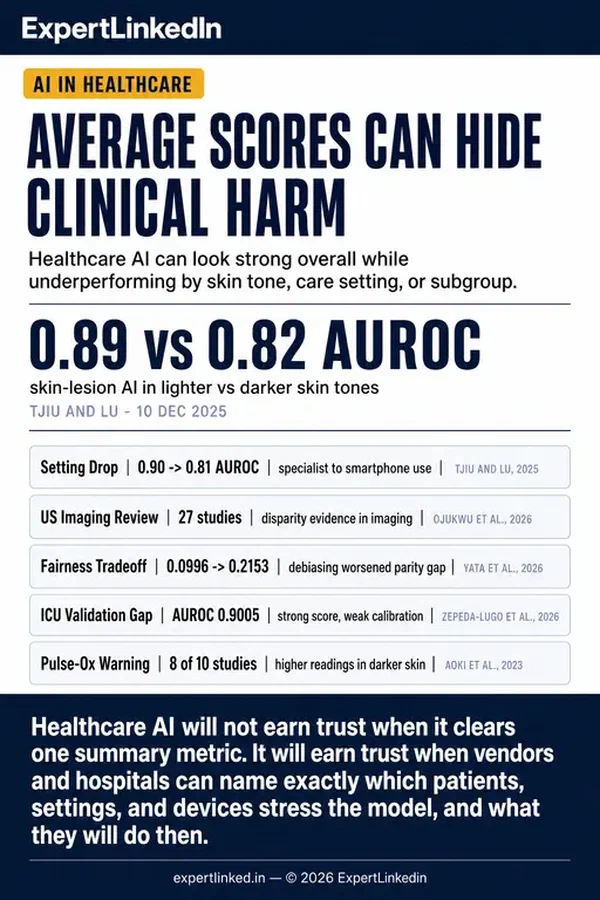
A strong average score can hide the patients and care settings where healthcare AI breaks. Skin-tone gaps, validation shortcuts, and weak postmarket monitoring make subgroup evidence more important than another headline AUROC.